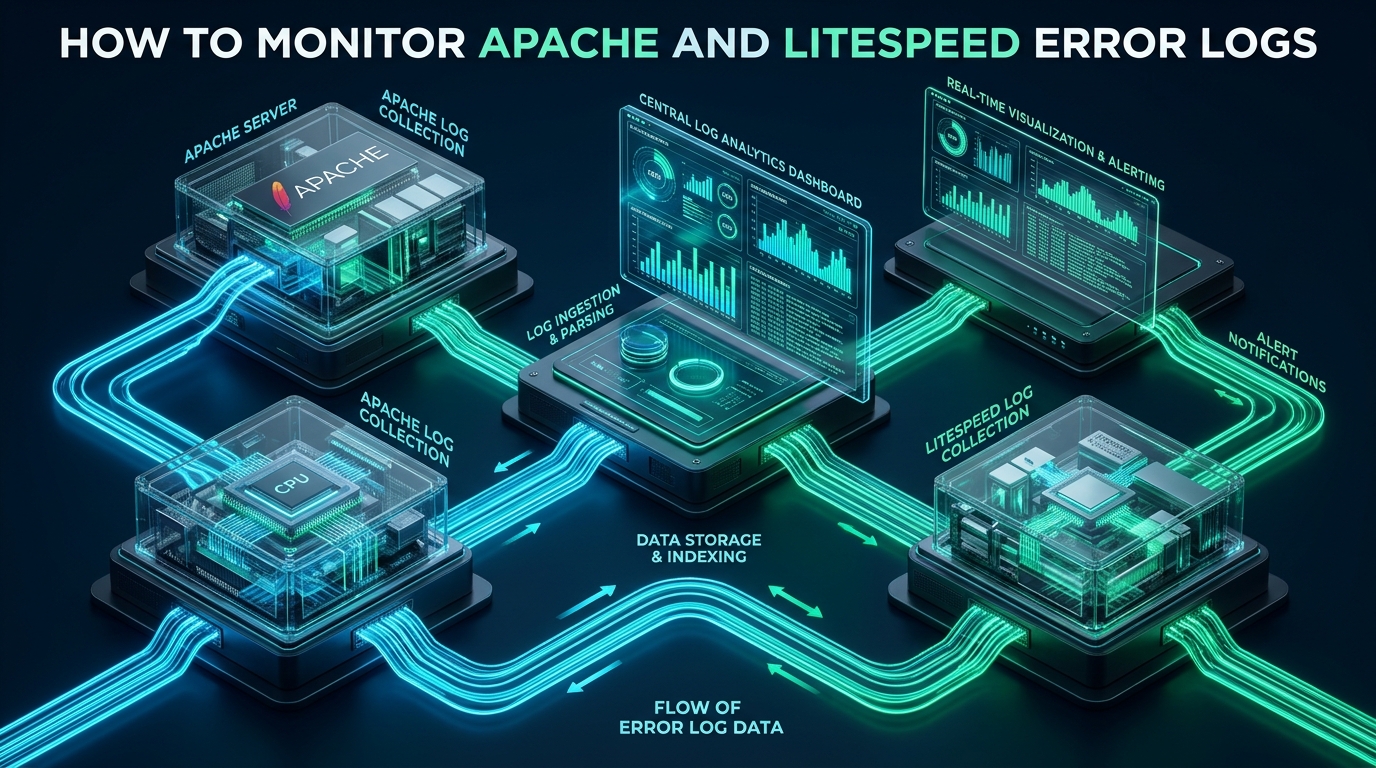
In high-concurrency production environments and distributed web hosting clusters, silent upstream timeouts, worker thread exhaustion, and fatal application crashes register in server error logs long before synthetic monitors or edge health checks trigger alarms. When managing complex multi-tenant architectures, operating without real-time log stream observability inevitably leads to blind spots, protracted mean time to repair (MTTR), and cascading server outages. At MeraHost, maintaining mission-critical WordPress infrastructure and high-frequency compute nodes on enterprise NVMe hardware requires sub-second error log telemetry and automated stream analytics to maintain unyielding five-nines platform availability.
How to Monitor Apache and LiteSpeed Error Logs: Architecture, Pipelines, and Triage
/var/log/apache2/error.log, /var/log/httpd/error_log, and /usr/local/lsws/logs/error.log) using systemd journalctl, continuous tail utilities, or low-overhead log forwarders like Vector and Fluent Bit. By tuning LogLevel, deploying structured JSON error schemas, and routing anomalies into centralized visualization clusters, sysadmins achieve immediate detection of worker exhaustion, PHP-FPM socket drops, and SSL renegotiation faults with near-zero performance overhead.
Web server error logs represent the definitive ground truth of your hosting environment. Unlike standard HTTP access logs—which merely record request ingress, HTTP status codes, and user-agent strings—error logs capture kernel-level system call interruptions, shared-memory synchronization failures, backend FastCGI/LSAPI pipe breakages, and internal access control violations. Understanding how Apache HTTP Server and LiteSpeed Web Server (LSWS) handle error telemetry is essential for diagnosing high-load bottlenecks and hardening infrastructure against production failures.
While both web servers serve similar workloads, their internal concurrency models dictate profoundly different logging behaviors. Apache—relying on Multi-Processing Modules (MPMs) such as event or worker—writes error entries across partitioned thread pools, often incurring write contention on busy multi-core systems. Conversely, LiteSpeed Web Server employs an asynchronous, event-driven I/O loop paired with the LiteSpeed Server Application Interface (LSAPI), isolating worker stderr channels into dedicated high-throughput descriptors that minimize storage locks during cascading crash storms.
Log Topography: Standard Paths, Severities, and Virtual Host Isolation
Before constructing automated ingestion pipelines, systems administrators must map out the standard filesystem locations where error telemetry lands across different Linux distributions and control panel environments. Because distributions apply divergent default directory conventions, locating the correct log file requires an understanding of your target operating system’s filesystem layout.
Apache Error Log Hierarchy
On Debian and Ubuntu platforms, the primary system-wide Apache error log is located at /var/log/apache2/error.log. On Enterprise Linux derivatives such as RHEL, AlmaLinux, Rocky Linux, and CentOS, the daemon runs under the binary name httpd, directing its master error log to /var/log/httpd/error_log. In production environments hosting multiple virtual hosts (vhosts), global logging should always be augmented by dedicated per-domain log directives:
- Debian/Ubuntu Global:
/var/log/apache2/error.log - RHEL/AlmaLinux Global:
/var/log/httpd/error_log - cPanel / WHM Virtual Hosts:
/etc/apache2/logs/error_log(global) and/home/{username}/logs/{domain}.error.log(per-vhost) - Virtualmin / Custom Panels:
/var/log/virtualmin/{domain}_error_log
LiteSpeed Web Server Log Hierarchy
LiteSpeed Web Server installs cleanly into a self-contained root tree at /usr/local/lsws/ across all Linux distributions. Unlike Apache, LiteSpeed categorizes operational runtime events and unhandled process crashes across distinct files:
- Server Master Error Log:
/usr/local/lsws/logs/error.log— Contains web engine startups, SSL handshake errors, rewrite evaluation notices, mod_security triggers, and connection state anomalies. - Process Stderr Log:
/usr/local/lsws/logs/stderr.log— Captures uncaught PHP fatal errors, memory limit terminations, C-extension segmentation faults, and unbuffered stdout/stderr emissions from external LSAPI processes. - Virtual Host Error Logs:
/usr/local/lsws/conf/vhosts/{vhost}/error.logor configured domain directories such as/home/{username}/logs/error.login cPanel/DirectAdmin integrated setups.
Architecture Note: When troubleshooting catastrophic 503 Service Unavailable errors on LiteSpeed, never limit your inspection to
error.logalone. When an externallsphpprocess encounters a memory leak, segfault, or exceeds operating system resource quotas (such as CloudLinux LVE constraints), the crash footprint is written directly tostderr.logbefore the web server can synthesize an internal error notification.
Comparative Matrix: Apache vs. LiteSpeed Error Logging Architecture
To effectively monitor server error logs at enterprise scale, engineers must recognize the fundamental differences in how both engines serialize log events under heavy I/O load. Under sustained traffic surges of 25,000+ requests per second, synchronous disk writes from thousands of concurrent threads can saturate filesystem write queues, inducing catastrophic thread serialization. The comparative matrix below outlines the critical architectural specifications between standard Apache configurations and optimized LiteSpeed deployments:
| Feature / Metric | Standard Apache (Default) | LiteSpeed Enterprise (Tuned) |
|---|---|---|
| Log File Writing Mechanism | Synchronous POSIX write() with process lock contention | Asynchronous non-blocking event-driven ring buffer |
| CPU I/O Overhead Under Heavy Concurrency | 6% – 14% CPU spent in iowait and kernel mutex locks | < 0.5% CPU overhead on Enterprise NVMe arrays |
| Crash Telemetry Isolation (PHP/FastCGI) | Interleaved into global error_log or lost in pipe buffer | Dedicated stderr.log stream capturing segfaults and OOMs |
| Log Ingestion & Buffer Latency | 30ms – 80ms buffer flush delays depending on MPM state | Instantaneous sub-millisecond inode emission |
| Log Rotation Signal Impact | Graceful reload (SIGHUP) recycles active worker threads | Zero-downtime atomic inode reopen via SIGUSR1 signal |
| Structured JSON Error Formatting | Requires mod_log_config format strings (Apache 2.4+) | Native high-efficiency JSON output and Logstash integration |
Production Configuration: Hardened Server Log Directives
Default error logging configurations are intentionally generic. In production, default directives either produce massive volumes of trivial SSL handshake noise that inundate storage disks, or fail to capture essential forensic data such as client IPs, SSL protocol versions, and internal request correlation IDs. Below are verified production configuration files optimized for enterprise stability.
1. Apache 2.4+ Hardened Error Logging Configuration
This configuration tunes Apache’s global LogLevel, isolates virtual host error streams, suppresses non-actionable SSL handshake drops, and configures microsecond timestamp resolution. Save this file to /etc/apache2/conf-available/enterprise-error-logging.conf on Ubuntu/Debian or /etc/httpd/conf.d/enterprise-error-logging.conf on RHEL/AlmaLinux:
# /etc/apache2/conf-available/enterprise-error-logging.conf
# Enterprise Error Log Architecture - Production Hardened Specification

# Global LogLevel Configuration: warn overall, debug per-module if needed
LogLevel warn ssl:error rewrite:warn socache_shmcb:error

# Global Error Log Destination with Microsecond Precision Format
ErrorLog /var/log/apache2/error.log

# Custom Error Log Format String (Apache 2.4.30+)
# Enforces ISO 8601 Microsecond Timestamps, Module Origin, Process ID, and Client IP
ErrorLogFormat "[%{cu}t] [%-m:%-l] [pid %P:tid %T] %7F: %E: [client\ %a] %M%connection"

# Per-VirtualHost Directive Template
<VirtualHost *:443>
    ServerName enterprise.example.com
    DocumentRoot /var/www/enterprise/public_html

    # Domain-isolated error log preventing noisy-neighbor blind spots
    ErrorLog /var/log/apache2/enterprise.example.com_error.log

    # Enforce request unique identifier correlation (requires mod_unique_id)
    <IfModule mod_unique_id.c>
        ErrorLogFormat "[%{cu}t] [%-m:%-l] [pid %P:tid %T] [%{UNIQUE_ID}e] [client\ %a] %M"
    </IfModule>

    # SSL Logging Controls: Suppress client renegotiation spam
    SSLEngine on
    SSLCertificateFile /etc/ssl/certs/example.crt
    SSLCertificateKeyFile /etc/ssl/private/example.key
</VirtualHost>
2. LiteSpeed Web Server Production Log Specification
In LiteSpeed Web Server, logging directives are defined within the central configuration file at /usr/local/lsws/conf/httpd_config.conf or managed via the LiteSpeed WebAdmin Console (Server Configuration > Log). The configuration below establishes asynchronous buffer limits, disables noisy debug tracing, and configures automated size-based rollbacks:
# /usr/local/lsws/conf/httpd_config.conf (Server Log Stanza)
# LiteSpeed Enterprise Non-Blocking Log Telemetry Configuration

errorlog $SERVER_ROOT/logs/error.log {
    # Logging Level: DEBUG, INFO, NOTICE, WARN, ERROR
    # In production, use WARN or NOTICE. NEVER leave DEBUG active under production load!
    logLevel                WARN

    # Debug Level: 0 = None, 10 = Minimal, 20 = Detailed, 100 = Packet Tracing
    debugLevel              0

    # Rolling Size: Automatically rotate when file reaches 200MB
    rollingSize             209715200

    # Keep up to 10 rotated archives
    keepDays                10

    # Compress rotated logs with gzip to conserve NVMe storage
    compressArchive         1

    # Enable asynchronous file writes (0 = Sync, 1 = Async non-blocking ring buffer)
    enableAsyncLog          1
}

# Dedicated Stderr Capture for LSAPI Worker Processes
accessLog $SERVER_ROOT/logs/stderr.log {
    rollingSize             104857600
    keepDays                7
    compressArchive         1
}
Architecture Note: Setting
debugLevel 10or higher on LiteSpeed under high concurrency forces the web server to write verbose state transition traces for every micro-operation. This can generate over 5GB of log data per hour, degrading NVMe storage throughput and spiking CPU kernel lock times. Always verify thatdebugLevelis strictly set to0across all production virtual hosts.
Real-Time CLI Triage: Tail, Grep, Journalctl, and AWK Recipes
When an incident occurs in real time, engineers cannot wait for batch indexing pipelines to digest gigabytes of raw logs. High-velocity incident response demands command-line mastery using standard Linux core utilities. Below are essential shell recipes for isolating active server degradation on live systems.
1. Continuous Live Triage with Tail and Regex Filtering
To monitor server error logs on Apache in real time while filtering out routine notice messages, execute:
# Stream Apache errors filtered strictly by critical severity levels
tail -Fn 50 /var/log/apache2/error.log | grep --line-buffered -E "\[:(error|crit|alert|emerg)\]"

# Stream LiteSpeed master error log and stderr simultaneously using multitail or tail
tail -Fn 50 /usr/local/lsws/logs/error.log /usr/local/lsws/logs/stderr.log
2. Isolating Top Offending IP Addresses and Request URIs
When a web application suffers a distributed brute-force attack or vulnerability scan, analyzing the frequency of client IP addresses generating errors provides immediate actionable intelligence for your firewall:
# Extract and sort the top 10 IP addresses triggering Apache error log entries
grep "client" /var/log/apache2/error.log | awk -F'\[client ' '{print $2}' | awk '{print $1}' | tr -d ']' | sort | uniq -c | sort -rn | head -n 10

# Count the most frequent error messages in LiteSpeed error.log over the last 50,000 lines
tail -n 50000 /usr/local/lsws/logs/error.log | awk -F'\[ERROR\]' '{print $2}' | sort | uniq -c | sort -rn | head -n 10
3. Deep Journalctl Inspection for Process Aborts and OOM Events
When systemd manages the web daemon, kernel kills and process crashes bypass standard text logs and land in the systemd binary journal. Querying journalctl allows you to identify systemd cgroup kills and out-of-memory (OOM) invocations:
# Inspect Apache systemd service errors over the past 30 minutes
journalctl -u apache2 --since "30 min ago" -p err..emerg --no-pager

# Check for LiteSpeed daemon terminations, segfaults, and kernel cgroup kills
journalctl -u lshttpd -g "killed|crash|dumped|core" --since "2 hours ago"
Automated Ingestion Pipeline: Streaming Logs with Vector
Manual CLI triage is indispensable during acute operational crises, but modern enterprise engineering requires automated log stream aggregation. Legacy agents like Logstash or standard rsyslog often introduce significant memory overhead (consuming 500MB+ of RAM) or drop events under disk backpressure.
At MeraHost Enterprise Cloud, we recommend deploying Vector—a high-performance, memory-safe observability agent written in Rust. Vector consumes less than 35MB of RAM while processing over 100,000 log events per second. Below is a complete, runnable Vector configuration that tails both Apache and LiteSpeed error streams, parses raw strings into structured JSON using Vector Remap Language (VRL), and ships them to a central OpenSearch, Elasticsearch, or ClickHouse analytics cluster:
# /etc/vector/vector.yaml
# Production Error Log Aggregation Pipeline for Apache & LiteSpeed

sources:
  apache_errors:
    type: file
    include:
      - "/var/log/apache2/*error.log"
      - "/var/log/httpd/*error_log"
    read_from: beginning
    ignore_older_secs: 86400

  litespeed_errors:
    type: file
    include:
      - "/usr/local/lsws/logs/error.log"
      - "/usr/local/lsws/logs/stderr.log"
    read_from: beginning
    ignore_older_secs: 86400

transforms:
  parse_apache:
    type: remap
    inputs: ["apache_errors"]
    source: |
      .server_engine = "apache"
      .host = get_hostname!()
      # Parse Apache 2.4 default error format using regex
      parsed, err = parse_regex(.message, r'^\[(?P<timestamp>[^\]]+)\] \[(?:(?P<module>[\w_]+):)?(?P<level>[\w]+)\] (?:\[pid (?P<pid>\d+):tid (?P<tid>\d+)\] )?(?:\[client (?P<client_ip>[^\]]+)\] )?(?P<error_msg>.*)$')
      if err == null {
        .@timestamp = parsed.timestamp
        .severity = upcase(parsed.level)
        .module = parsed.module
        .pid = to_int(parsed.pid) ?? 0
        .client_ip = parsed.client_ip
        .message = parsed.error_msg
      }

  parse_litespeed:
    type: remap
    inputs: ["litespeed_errors"]
    source: |
      .server_engine = "litespeed"
      .host = get_hostname!()
      # Parse LiteSpeed format: 2026-10-28 06:12:30.123 [LEVEL] [PID] Message
      parsed, err = parse_regex(.message, r'^(?P<timestamp>\d{4}-\d{2}-\d{2} [\d:.]+)\s+\[(?P<level>\w+)\]\s+\[(?P<pid>\d+)\]\s+(?P<error_msg>.*)$')
      if err == null {
        .@timestamp = parsed.timestamp
        .severity = upcase(parsed.level)
        .pid = to_int(parsed.pid) ?? 0
        .message = parsed.error_msg
      }

sinks:
  central_elasticsearch:
    type: elasticsearch
    inputs: ["parse_apache", "parse_litespeed"]
    endpoints: ["https://logs.internal.enterprise:9200"]
    auth:
      strategy: basic
      user: "${LOGS_USER}"
      password: "${LOGS_PASSWORD}"
    index: "webserver-errors-%Y.%m.%d"
    compression: gzip
    tls:
      verify_certificate: true
    buffer:
      type: disk
      max_size: 2147483648 # 2GB Disk Buffer for network resilience
Hardened Log Rotation: Zero-Downtime Atomic Logrotate
Without automated log rotation, high-traffic servers will eventually exhaust available disk inodes or fill root partitions, resulting in emergency server lockups. However, improperly configured log rotation that issues hard service restarts (such as systemctl restart apache2) drops active TCP sessions and terminates in-flight database transactions.
The production logrotate configuration below utilizes atomic log file truncation and POSIX signal notifications (SIGUSR1) to trigger seamless file descriptor reallocation without interrupting a single incoming visitor connection:
# /etc/logrotate.d/webservers-hardened
# Production Atomic Log Rotation for Apache and LiteSpeed

/var/log/apache2/*.log /var/log/httpd/*log {
    daily
    missingok
    rotate 14
    compress
    delaycompress
    notifempty
    create 0640 www-data adm
    sharedscripts
    prerotate
        if [ -d /etc/logrotate.d/httpd-prerotate ]; then             run-parts /etc/logrotate.d/httpd-prerotate;         fi;     endscript
    postrotate
        # Issue Graceful Restart (SIGUSR1) to Apache workers without dropping active connections
        if systemctl is-active --quiet apache2; then             systemctl reload apache2 > /dev/null 2>&1;         elif systemctl is-active --quiet httpd; then             /usr/sbin/apachectl graceful > /dev/null 2>&1;         fi;
    endscript
}

/usr/local/lsws/logs/error.log /usr/local/lsws/logs/stderr.log {
    daily
    missingok
    rotate 14
    compress
    delaycompress
    notifempty
    create 0640 lsadm nogroup
    sharedscripts
    postrotate
        # Notify LiteSpeed engine to re-open log file handles instantly without restarting
        if [ -f /tmp/lshttpd/lshttpd.pid ]; then             kill -USR1 $(cat /tmp/lshttpd/lshttpd.pid) > /dev/null 2>&1;         elif systemctl is-active --quiet lshttpd; then             systemctl kill -s USR1 lshttpd > /dev/null 2>&1;         fi;
    endscript
}
Critical Error Signatures and Root-Cause Remediation
When analyzing server error streams, specific log signatures recur across production deployments. Knowing how to immediately translate raw error strings into specific kernel, daemon, or application fixes reduces downtime from hours to minutes.
1. Apache: “server reached MaxRequestWorkers setting”
Log String: [mpm_event:error] [pid 1420:tid 139] AH00161: server reached MaxRequestWorkers setting, consider raising the MaxRequestWorkers setting
Root Cause: All available Apache worker threads are occupied handling slow requests, keepalive stalls, or backend PHP-FPM delays. Inbound requests are queued in the TCP listen backlog or dropped.
Remediation: Increase ServerLimit and MaxRequestWorkers inside /etc/apache2/mods-available/mpm_event.conf while validating that physical RAM can accommodate the expanded thread pool. Simultaneously verify that backend PHP-FPM pools are not deadlocking on long-running database queries.
2. LiteSpeed: “[LSAPI] Connection to [UID:…] closed: unexpected end of stream”
Log String: [ERROR] [LSAPI] Connection to [/tmp/lshttpd/lsphp.sock] closed: unexpected end of stream
Root Cause: The underlying lsphp worker process crashed violently. Common triggers include PHP memory ceiling exhaustion (memory_limit reached), a corrupt OPcache segment, or an unhandled segmentation fault in an extension such as Imagick or cURL.
Remediation: Inspect /usr/local/lsws/logs/stderr.log and /var/log/messages. Look for Linux kernel OOM-killer invocations (Out of memory: Kill process). Increase the PHP memory limit in php.ini and raise Memory Soft Limit (bytes) and Memory Hard Limit (bytes) under the External Application configuration in LiteSpeed WebAdmin.
3. Both: “SSL Library Error: error:14094412:SSL routines:ssl3_read_bytes:sslv3 alert bad certificate status response”
Root Cause: OCSP Stapling is enabled, but the upstream Certificate Authority’s OCSP responder timed out or returned an expired response, causing browsers to reject the TLS handshake.
Remediation: Verify DNS resolver latency on the host server. Ensure /etc/resolv.conf points to redundant, high-speed resolvers (e.g., 1.1.1.1 and 8.8.8.8). In Apache, configure SSLStaplingResponderTimeout 5 and SSLStaplingReturnResponderErrors off to prevent client aborts when external CA responders experience transient edge outages.
Frequently Asked Questions
What is the primary difference between access logs and error logs in Apache and LiteSpeed?
Access logs track all incoming HTTP transactions (IP address, timestamp, HTTP verb, URI, status code, and bytes transferred), providing analytics on web traffic volume and page visits. In contrast, error logs record diagnostic failure events, daemon startup sequences, process crashes, permission denials, and backend FastCGI/LSAPI connection aborts. Access logs tell you what visitors requested; error logs tell you why the server or application failed to process the request properly.
Why is LiteSpeed stderr.log separate from error.log, and when should I inspect it?
LiteSpeed maintains an architectural distinction between web engine operations and external worker process streams. The primary error.log captures web server events like SSL negotiations and mod_security rules. The stderr.log file directly captures standard error streams from decoupled external application runners (such as lsphp, Node.js, or Python WSGI processes). Whenever an application returns a 503 Service Unavailable or crashes due to segmentation faults and PHP fatal memory exhaustion, the diagnostic stack trace is recorded in stderr.log.
Does setting Apache or LiteSpeed to debug LogLevel impact web server performance?
Yes, significantly. In production, setting LogLevel debug in Apache or a high debugLevel in LiteSpeed forces the web server to write detailed tracing for every microsecond state transition, regex evaluation, and header parsing step. Under high concurrency, this generates hundreds of megabytes of disk I/O per minute, triggering severe filesystem lock contention and degrading request throughput by 30% to 60%. Always restrict production logging to warn or notice, reserving debug levels strictly for staging environments.
How can I rotate web server error logs without dropping active visitor connections?
To rotate logs seamlessly without dropping in-flight traffic, configure logrotate with the sharedscripts and postrotate directives to issue non-disruptive signals rather than a hard service restart. For Apache, send a graceful reload signal via systemctl reload apache2 or apachectl graceful (SIGUSR1). For LiteSpeed Web Server, send a SIGUSR1 signal directly to the master daemon PID (kill -USR1 $(cat /tmp/lshttpd/lshttpd.pid)). Both servers will immediately re-open file descriptors to the new log file while continuing to service active HTTP connections without interruption.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).