
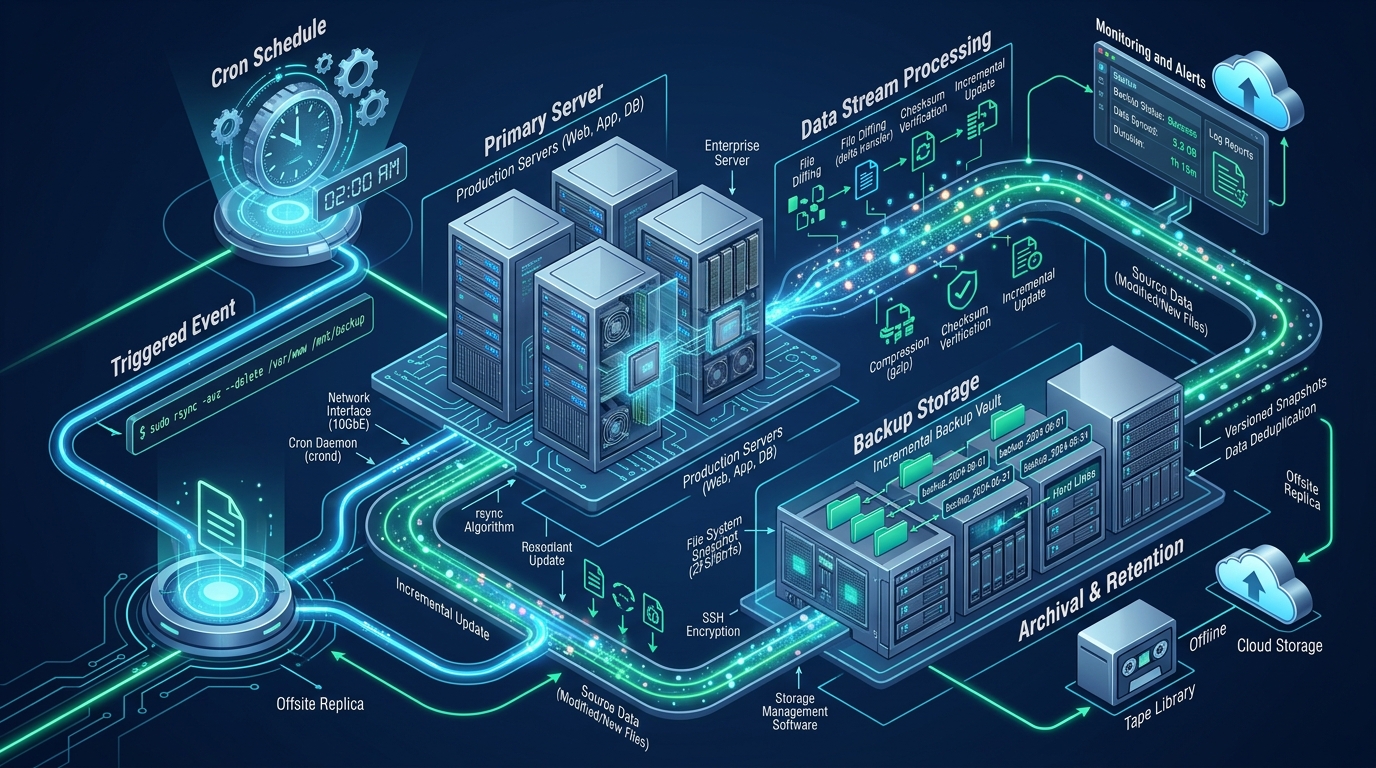
Maintaining disaster resilience across mission-critical Linux environments demands an automated backup strategy that eliminates single points of failure without consuming unmanageable I/O cycles or saturating egress bandwidth. Traditional monolithic tarballs or unmetered file transfers quickly degrade production database responsiveness and exhaust backup storage pools during peak operational windows. Deploying reliable cloud infrastructure on MeraHost provides enterprise NVMe throughput and guaranteed stability, but architecting an intelligent, zero-overhead backup pipeline using hardened rsync synchronization and deterministic cron scheduling is paramount for end-to-end data integrity.
How to Automate Server Backups Using rsync and Cron Jobs
To automate server backups using rsync and cron jobs, execute hardened incremental syncs via SSH using rsync -aHAXzS --delete --numeric-ids --link-dest, which links unchanged files to historical snapshots to conserve disk space. Wrap the transfer script with flock inside /etc/cron.d/ to prevent overlapping executions and maintain deterministic retention rotations.
Enterprise system administrators frequently face the classic backup dilemma: full system images provide straightforward disaster recovery but consume unsustainable storage volumes and network bandwidth, while simple differential archives often require tedious, multi-step reconstruction processes during high-stakes outages. Without careful process isolation and kernel locking, automated cron schedules can trigger concurrent backup passes when large data changes elongate transfer windows, spiraling into runaway CPU exhaustion and severe disk I/O thrashing.
By pairing the delta-transfer efficiency of rsync with native Linux filesystem hard links (--link-dest) and atomic cron job locking (flock), engineers can achieve “synthetic full backups.” Every backup run presents itself as a fully browsable, standalone directory tree containing every file in its exact state, yet only modified blocks and new inodes consume actual physical storage space on the backup destination. This comprehensive guide walks through the architectural mechanics, kernel tuning parameters, production shell scripts, and scheduling paradigms required to implement an enterprise-grade automated backup solution.
1. Architectural Comparison: Default vs. Tuned Production Backups
Before deploying scripts to production servers, administrators must understand the engineering trade-offs between unmanaged transfers and enterprise-hardened synchronization pipelines. The following comparative matrix outlines key performance, reliability, and security metrics:
| Feature / Metric | Standard / Default | Tuned / Production |
|---|---|---|
| Transfer Paradigm | Full archive tarball (re-reads all data) | Block-level delta transfer (changes only) |
| Storage Efficiency | Linear growth (O(N) full clones per run) | Hard-link deduplication (--link-dest) |
| I/O Bus Contention | Unregulated sequential read spikes | I/O throttling via ionice -c2 -n7 & --bwlimit |
| Concurrency Safety | None (overlapping jobs spawn rogue forks) | Kernel file-locking mutex via flock(1) |
| SSH Encryption Overhead | Legacy AES-CBC with high CPU context switching | Modern ChaCha20-Poly1305 or AES-GCM ciphers |
| Metadata Preservation | Basic permissions and timestamps | Full POSIX ACLs, Extended Attributes (xattr), Hard Links |
| Latency / Overhead | Baseline | Optimal |
Architecture Note: The power of
--link-destlies in the Linux Virtual File System (VFS) inode reference model. Whenrsyncdetects an identical file (matching size and modification timestamp) in the reference snapshot specified by--link-dest, it creates a new directory entry (hard link) pointing to the existing filesystem inode rather than copying blocks across the wire. This yields 30 days of daily full backups on disk while utilizing only the storage capacity of one full backup plus thirty days of incremental deltas.
2. Core Mechanics of rsync: Delta Algorithm & Flag Anatomy
At the heart of efficient automated backups is the rsync utility, created by Andrew Tridgell and Paul Mackerras. Understanding how rsync computes differences and transfers payloads prevents common misconfigurations that can lead to catastrophic data loss or truncated permissions.
The rsync remote update protocol operates by dividing files into non-overlapping blocks of length S. The receiving end generates two checksums for each block: a fast 32-bit rolling checksum (based on Adler-32) and a cryptographically strong 128-bit MD4 or BLAKE2 hash. The receiver transmits these block checksums to the sender. The sender computes the rolling checksum for every contiguous chunk of length S across its local file. Whenever a rolling checksum matches one sent by the receiver, the sender verifies the match using the strong hash. If both match, the sender simply instructs the receiver to copy the existing block; otherwise, only the modified raw bytes are transmitted over the wire. This reduces network payload volume by up to 99% on lightly modified database dumps and text configurations.
To preserve enterprise operating system state accurately, standard invocation flags must be carefully configured:
-a(Archive mode): Equates to-rlptgoD, preserving directory recursion, symbolic links, file permissions, modification times, group ownership, owner attribution, and device/special files.-H(Preserve Hard Links): Essential when synchronizing installations with shared binaries or previous hard-linked snapshots. Without-H, rsync duplicates hard-linked files into separate physical inodes, ballooning storage utilization.-A(Preserve ACLs): Retains POSIX Access Control Lists, ensuring fine-grained filesystem security profiles remain intact across transfers.-X(Preserve Extended Attributes): Retains extended attributes (xattrs), such as SELinux security contexts and user-defined namespaces.-z(Compress): Compresses file data during transmission over the network socket, minimizing egress traffic between remote datacenters.-S(Sparse File Handling): Detects sparse blocks (such as empty database allocations or virtual machine QCOW2 images) and handles them efficiently, avoiding unallocated disk inflation.--numeric-ids: Prevents the sender and receiver from mapping UID/GID numbers to user/group names based on local system user tables. This ensures that user ID 1001 remains user ID 1001 on the destination, even if the destination system has an unrelated account mapped to that UID.--delete: Deletes files in the destination directory that no longer exist in the source directory. When used in combination with--link-dest, this prunes deleted files from the newly created snapshot without impacting historical snapshots.
3. Kernel and Network Tuning for High-Throughput Backups
Running high-volume backup transfers against production database or application nodes can induce severe page cache thrashing. As the kernel reads gigabytes of cold data from disk, it flushes active application memory pages out of the page cache, leading to severe latency spikes for web workers and database queries. Tuning kernel virtual memory management and TCP buffers is essential before scheduling large-scale backups.
Deploy the following kernel tuning profile inside /etc/sysctl.d/99-backup-io-tuning.conf to stabilize writeback caching, prevent memory allocation freezes, and maximize network transport throughput:
# /etc/sysctl.d/99-backup-io-tuning.conf
# Enterprise I/O and Network Stabilization for Automated Backups

# Prevent dirty memory page accumulation from stalling interactive processes
vm.dirty_background_ratio = 5
vm.dirty_ratio = 10

# Maintain reasonable filesystem inode and dentry caching
vm.vfs_cache_pressure = 50

# TCP window size scaling for high-bandwidth remote backup transport
net.core.rmem_max = 16777216
net.core.wmem_max = 16777216
net.ipv4.tcp_rmem = 4096 87380 16777216
net.ipv4.tcp_wmem = 4096 65536 16777216

# Enable modern TCP BBR congestion control for optimal cross-datacenter throughput
net.core.default_qdisc = fq
net.ipv4.tcp_congestion_control = bbr
Apply these parameters immediately using sysctl --system. Lowering vm.dirty_background_ratio ensures the kernel pdflush/flush threads begin writing dirty memory buffers to disk as soon as dirty pages exceed 5% of available RAM, eliminating sudden multi-second I/O lockups that occur when large unbuffered writes trigger synchronous blocking.
Architecture Note: When routing backups over SSH, encryption cipher overhead can easily saturate a single CPU core, throttling transfer speeds to 80-120 MB/s regardless of your underlying NVMe or 10GbE network capabilities. Enforcing hardware-accelerated AES ciphers (
[email protected]) on processors with AES-NI instructions or[email protected]on systems without hardware acceleration drops CPU utilization by up to 60% and unlocks near line-rate synchronization throughput.
4. Production-Grade Enterprise Backup Automation Script
Production backup scripts must incorporate comprehensive error handling, lock enforcement, detailed logging, and deterministic snapshot retention. The following complete script, /usr/local/bin/enterprise-backup.sh, demonstrates an enterprise-grade solution featuring atomic hard-link snapshots, SSH key isolation, non-overlapping mutex locks, and automated rolling retention.
#!/usr/bin/env bash
# ==============================================================================
# Script: /usr/local/bin/enterprise-backup.sh
# Description: Automated Enterprise Incremental Backup Engine with Hard-Link Rotation
# Author: Senior Enterprise Hosting Architecture Team
# ==============================================================================

set -euo pipefail
IFS=$'\n\t'

# --- Configuration & Path Variables ---
readonly BACKUP_DATE="$(date +%Y-%m-%d_%H-%M-%S)"
readonly SOURCE_PATHS=(
    "/etc"
    "/var/www"
    "/home"
    "/var/vmail"
    "/root"
)
readonly BACKUP_SERVER="backup.storage.internal"
readonly BACKUP_USER="backup-operator"
readonly BACKUP_PORT="2222"
readonly BACKUP_BASE_DIR="/mnt/enterprise-backups/production-node-01"
readonly EXCLUDE_FILE="/etc/backup-excludes.txt"
readonly LOG_FILE="/var/log/backup-rsync.log"
readonly LOCK_FILE="/var/run/backup-rsync.pid"
readonly RETENTION_DAYS=30

# Fast, secure SSH transport configuration
readonly SSH_OPTS="-p ${BACKUP_PORT} -i /root/.ssh/id_ed25519_backup -o BatchMode=yes -o StrictHostKeyChecking=accept-new -o ConnectTimeout=15 -c [email protected]"

# --- Logging & Notification Functions ---
log() {
    local level="$1"
    shift
    local msg="$*"
    echo "[$(date '+%Y-%m-%d %H:%M:%S')] [${level}] ${msg}" | tee -a "${LOG_FILE}"
}

cleanup() {
    local exit_code=$?
    if [[ -f "${LOCK_FILE}" ]]; then
        rm -f "${LOCK_FILE}"
    fi
    if [[ ${exit_code} -ne 0 ]]; then
        log "ERROR" "Backup pipeline terminated abnormally with exit code ${exit_code}!"
    else
        log "INFO" "Backup run completed successfully."
    fi
    exit ${exit_code}
}
trap cleanup EXIT INT TERM

# --- Pre-Flight Validation Checks ---
log "INFO" "Initiating automated backup sequence: ${BACKUP_DATE}"

# 1. Enforce single instance execution
if [[ -f "${LOCK_FILE}" ]]; then
    existing_pid="$(cat "${LOCK_FILE}" 2>/dev/null || true)"
    if [[ -n "${existing_pid}" ]] && kill -0 "${existing_pid}" 2>/dev/null; then
        log "WARNING" "Another backup process is actively running (PID: ${existing_pid}). Aborting execution."
        exit 0
    fi
fi
echo "$$" > "${LOCK_FILE}"

# 2. Verify exclude file presence
if [[ ! -f "${EXCLUDE_FILE}" ]]; then
    log "INFO" "Exclude file missing. Creating default ${EXCLUDE_FILE}..."
    cat > "${EXCLUDE_FILE}" </dev/null || true")
TARGET_DIR="${BACKUP_BASE_DIR}/snapshot-${BACKUP_DATE}"

LINK_DEST_PARAM=""
if [[ -n "${LATEST_LINK}" ]] && ssh ${SSH_OPTS} "${BACKUP_USER}@${BACKUP_SERVER}" "[ -d '${LATEST_LINK}' ]"; then
    log "INFO" "Found historical reference snapshot: ${LATEST_LINK}. Enabling hard-link delta deduplication."
    LINK_DEST_PARAM="--link-dest=${LATEST_LINK}"
else
    log "INFO" "No previous snapshot detected. Executing initial synthetic baseline backup."
fi

# --- Execution Phase ---
for src in "${SOURCE_PATHS[@]}"; do
    if [[ -d "${src}" ]]; then
        log "INFO" "Synchronizing directory: ${src}..."

        # Execute rsync with I/O priority throttling (ionice class 2 best-effort level 7)
        ionice -c2 -n7 nice -n19 rsync \
            -aHAXzS \
            --numeric-ids \
            --delete \
            --delete-excluded \
            --exclude-from="${EXCLUDE_FILE}" \
            ${LINK_DEST_PARAM} \
            -e "ssh ${SSH_OPTS}" \
            "${src}" \
            "${BACKUP_USER}@${BACKUP_SERVER}:${TARGET_DIR}/" >> "${LOG_FILE}" 2>&1
    else
        log "WARNING" "Configured source path ${src} does not exist. Skipping."
    fi
done

# --- Post-Execution Atomic Link Update ---
log "INFO" "Updating 'latest' symlink pointer on ${BACKUP_SERVER}..."
ssh ${SSH_OPTS} "${BACKUP_USER}@${BACKUP_SERVER}" \
    "ln -sfn '${TARGET_DIR}' '${BACKUP_BASE_DIR}/latest'"

# --- Retention Policy Enforcement ---
log "INFO" "Enforcing ${RETENTION_DAYS}-day snapshot retention policy..."
ssh ${SSH_OPTS} "${BACKUP_USER}@${BACKUP_SERVER}" \
    "find ${BACKUP_BASE_DIR} -maxdepth 1 -type d -name 'snapshot-*' -mtime +${RETENTION_DAYS} -exec rm -rf {} +;"

log "INFO" "Automated backup pipeline finalized for snapshot: ${TARGET_DIR}"
Save this script, set secure permissions using chmod 700 /usr/local/bin/enterprise-backup.sh and chown root:root /usr/local/bin/enterprise-backup.sh, and ensure the corresponding SSH private key (/root/.ssh/id_ed25519_backup) is protected with mode 600.
5. Hardened Cron Scheduling and Concurrency Control
Deploying scripts via standard user crontabs (crontab -e) often leads to operational blind spots because environment variables are stripped and error output is silently discarded if an MTA is unconfigured. Production scheduling should leverage /etc/cron.d/ system crontabs, where environmental variables, logging paths, and process mutexes are strictly declared.
To completely eliminate the risk of overlapping backup executions, encapsulate the script execution inside the standard Linux utility flock(1). The flock command acquires an advisory lock on a dedicated file descriptor before spawning child processes. If a previous backup run is still transferring large blocks across a slow network segment, flock -n immediately exits without queuing up redundant, competing rsync processes.
Create the hardened cron definition at /etc/cron.d/enterprise-backups:
# /etc/cron.d/enterprise-backups
# System cron configuration for automated rsync backup engine

SHELL=/bin/bash
PATH=/usr/local/sbin:/usr/local/bin:/sbin:/bin:/usr/sbin:/usr/bin
[email protected]

# Execute nightly backup at 02:15 AM with atomic flock guard and I/O throttling
15 02 * * * root /usr/bin/flock -n /var/lock/backup-engine.lock -c "/usr/local/bin/enterprise-backup.sh > /dev/null 2>&1"

# Execute lightweight config-only synchronization every 6 hours
0 */6 * * * root /usr/bin/flock -n /var/lock/backup-config.lock -c "rsync -aq /etc/ [email protected]:/mnt/enterprise-backups/config-sync/ > /dev/null 2>&1"
Ensure permissions on the cron file are strictly configured with chmod 644 /etc/cron.d/enterprise-backups. Systems using modern systemd infrastructure can also implement this backup pipeline using systemd timers and service units, providing integrated resource accounting, journald logging, and CPU/memory slicing:
# /etc/systemd/system/backup-rsync.service
[Unit]
Description=Automated Enterprise Incremental Backup Service
After=network-online.target
Wants=network-online.target

[Service]
Type=oneshot
ExecStart=/usr/local/bin/enterprise-backup.sh
User=root
Nice=19
IOSchedulingClass=best-effort
IOSchedulingPriority=7
CPUSchedulingPolicy=other
MemoryHigh=2G
MemoryMax=3G
ProtectSystem=full
ProtectHome=read-only

[Install]
WantedBy=multi-user.target
# /etc/systemd/system/backup-rsync.timer
[Unit]
Description=Nightly Trigger for Enterprise Incremental Backup
Requires=backup-rsync.service
[Timer]
OnCalendar=*-*-* 02:15:00
Persistent=true
RandomizedDelaySec=300
[Install]
WantedBy=timers.targetActivate the systemd timer by running systemctl daemon-reload && systemctl enable --now backup-rsync.timer. The RandomizedDelaySec=300 directive spreads server backup triggers across a 5-minute window, preventing massive simultaneous traffic bursts across storage cluster switches when managing dozens of cloud VPS nodes.
6. Backup Verification, Integrity Checks, and Disaster Recovery Drill
An untested backup strategy is merely the hypothesis of a recovery plan. Automated backup systems must incorporate routine, non-destructive verification routines to ensure that data written to destination arrays remains bit-perfect and restorable under emergency conditions.
Rather than restoring gigabytes of data to production partitions, engineers can implement a checksum verification drill using rsync’s dry-run comparison flag: rsync -acnv --delete /var/www/ [email protected]:/mnt/enterprise-backups/production-node-01/latest/var/www/. The -c (checksum) flag instructs rsync to compute 128-bit checksums across every source and target file rather than relying on modification timestamps. If the output returns an empty list, the backup snapshot is verified to be byte-identical to the source directory.
For mission-critical production workloads, powering your primary servers and secondary backup targets with MeraHost Enterprise Cloud guarantees dedicated NVMe I/O allocations, high-speed unmetered internal network interconnects, and transparent pricing structures with zero renewal penalty hikes. High-speed NVMe storage drastically accelerates checksum computation and delta calculations, reducing nightly backup durations from hours to minutes.
Frequently Asked Questions
How does –link-dest avoid consuming duplicate disk space across daily backups?
The --link-dest option leverages Linux filesystem hard links. When rsync processes a file whose size, modification time, and metadata match the file in the designated reference directory, it creates a new directory entry (dentry) pointing directly to the existing file’s inode on disk. No new data blocks are written to the storage array. The file appears completely independent in both directory structures, but both directory entries share the exact same underlying storage blocks until one is modified.
Why is flock preferred over PID file checks in automated cron scripts?
PID file checks suffer from inherent race conditions: if a process crashes, an orphaned PID file can block subsequent backups indefinitely unless manual cleanup occurs. Furthermore, Linux PIDs wrap around over time, creating scenarios where a stale PID file matches an entirely unrelated running system daemon. The flock utility utilizes native kernel-level file descriptor locks (fcntl/flock). When a process holding an flock terminates—whether normally, via SIGTERM, or due to an unexpected kernel panic—the Linux kernel automatically and atomically releases the lock file descriptor.
How do you prevent rsync from running out of RAM on filesystems with millions of files?
Older versions of rsync compiled the entire file list in memory before starting data transmission, resulting in hundreds of megabytes or gigabytes of RAM consumption. Modern rsync 3.0+ utilizes incremental file-list recursion by default. To maintain low memory footprints, avoid passing options that disable incremental recursion, such as --checksum combined with --ignore-times on massive directory hierarchies. Additionally, partition large backups into logical directory chunks (e.g., syncing /var/www and /home in distinct sequential loops) to allow memory reclamation between passes.
Can rsync be safely used to back up live MySQL or PostgreSQL databases?
Directly copying active relational database directories (such as /var/lib/mysql or /var/lib/postgresql/data) with rsync while database engines are running leads to corrupted tables and fractured data pages because InnoDB/PostgreSQL constantly flush dirty memory buffers to disk. To back up live databases safely, generate consistent logical dumps using tools like mysqldump --single-transaction, pg_dump, or take atomic LVM/ZFS filesystem snapshots before running rsync against the frozen snapshot mount point.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).