
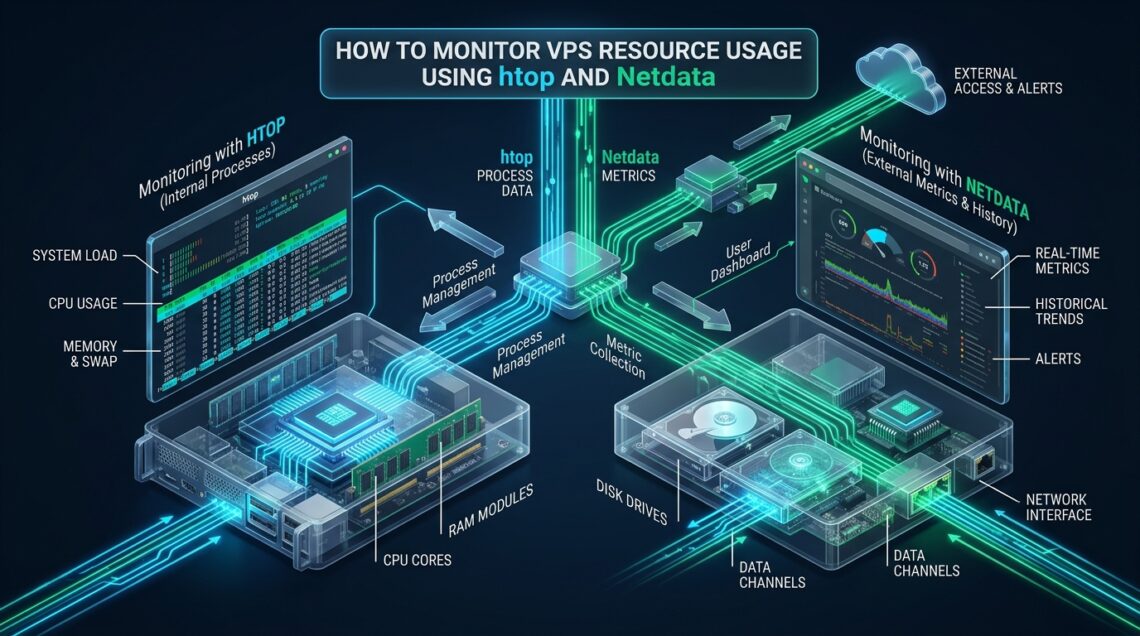
Managing high-concurrency production workloads on virtualized infrastructure requires real-time observability into how the Linux kernel schedules threads, manages memory page caches, and services storage I/O queues. When unexpected latency spikes degrade response times on unmonitored systems, systems engineers often scramble between disconnected command-line tools without clear visibility into hypervisor contention, CPU steal time, or memory pressure. Deploying high-availability infrastructure on MeraHost provides guaranteed bare-metal NVMe throughput, but maintaining optimal application performance still demands an authoritative, dual-layered monitoring strategy that pairs low-overhead terminal inspection with granular, continuous time-series telemetry.
How to Monitor VPS Resource Usage Using htop and Netdata
Direct Answer: To monitor VPS resources effectively, combine real-time interactive CLI inspection using htop for immediate process triage and thread profiling with distributed, continuous telemetry collection via Netdata for per-second metric resolution, historical anomaly detection, and automated alerting. This hybrid approach enables sub-second bottleneck identification across CPU, memory, disk I/O, and network stacks without degrading server throughput.
Understanding VPS Virtualization Telemetry: vCPUs, Memory Slices, and Storage Queues
Virtual Private Servers (VPS) operate under Kernel-based Virtual Machine (KVM) or containerized cgroups environments where hardware resources are partitioned, scheduled, and shared. Unlike dedicated bare-metal servers where telemetry directly reflects physical silicon execution, monitoring virtualized instances requires isolating hypervisor-induced overhead from application-level bottlenecks.
When observing Linux kernel metrics on a VPS instance, four core virtualization vectors must be monitored continuously:
- CPU Steal Time (
%st): Measures the percentage of time the virtual CPU had runnable threads ready for execution but was prevented from running by the hypervisor because the physical CPU cores were servicing other neighboring virtual machines. Any sustained steal time above 3% indicates severe hypervisor oversubscription. - Uninterruptible Sleep State (
DState) and I/O Wait (%wa): Processes blocked waiting for storage I/O or kernel locks enter theTASK_UNINTERRUPTIBLEstate. Highiowaitsignifies that CPU cycles are idle solely because disk operations—such as random SQLite/MySQL writes or swap operations—are backpressured. - Memory Cgroup Boundaries & OOM Killer Invocations: The Linux kernel aggressively uses inactive RAM for disk page caching (Buffers and Cached). In virtualized environments, failure to differentiate between dirty application allocations (Active/Anon) and reclaimable filesystem cache leads administrators to misdiagnose healthy caching as an imminent Out-Of-Memory (OOM) event.
- Network Socket Backlog & TCP Retransmissions: Sudden connection timeouts on web servers are frequently caused by ephemeral port exhaustion, syn-backlog overflows, or conntrack table saturation rather than raw bandwidth saturation.
Architecture Note: Commodity cloud hosting providers frequently oversubscribe physical CPU cores at ratios exceeding 4:1, resulting in unpredictable CPU steal spikes during peak business hours. On MeraHost Enterprise Cloud, all VPS compute nodes are provisioned on dedicated enterprise AMD EPYC and Intel Xeon processors with non-oversubscribed vCPU pinning and native PCIe Gen4 NVMe arrays, ensuring consistent zero-steal execution and sub-millisecond I/O latency.
Mastering htop: Real-Time Interactive Process and Thread Triage
While the traditional UNIX top utility has served system administrators for decades, its monochromatic display, lack of hierarchical thread visualization, and clunky process management make it inefficient during high-stress operational outages. htop is an enhanced, interactive ncurses-based process viewer designed for rapid diagnostics, dynamic sorting, and granular thread accounting.
Navigating the htop Interface and Color Encoding
The top section of the htop terminal interface provides immediate graphical metering across all provisioned vCPU cores, physical memory, and swap space. Understanding the specific color-coded segments allows engineers to assess subsystem health in fractions of a second:
- CPU Meters:
- Green: Normal-priority user-space execution threads.
- Blue: Low-priority (“niced”) user processes.
- Black / Dark Blue: Kernel-space system routines and syscall handling.
- Cyan: Steal time (vCPU waiting for hypervisor allocation).
- Orange / Amber: SoftIRQ and hard hardware interrupt processing.
- Memory Meters:
- Green: Used memory allocated by active user processes and resident sets.
- Blue: Buffer memory (temporary metadata buffers for block devices).
- Orange: Cache memory (page cache holding disk files in RAM for instantaneous read access).
Essential Hotkeys for SysAdmin Rapid Incident Response
Under operational triage, mastering htop keyboard shortcuts eliminates the need to run multiple diagnostic commands:
F5/t(Tree View): Toggles hierarchical process parent-child relationships. This reveals instantly whether an Nginx worker, PHP-FPM pool, or Node.js cluster is spawning runaway child processes.F4/\(Incremental Filter): Filters the live process table by executable name, user account, or argument string without stopping live updates.F6/>(Sort Column Selector): Instantly shifts the sorting priority between CPU percentage (PERCENT_CPU), Resident Memory (RES), Virtual Memory (VIRT), and Disk I/O rates.H: Toggles visibility of user-space threads. Hiding threads reduces visual clutter when auditing large multithreaded applications such as Java JVMs or MySQL.K: Toggles kernel thread visibility, hiding background kworkers and kswapd daemons to focus exclusively on application workloads.F9/k(Kill Signal): Sends standard POSIX signals (SIGTERM (15),SIGKILL (9),SIGHUP (1)) directly to selected processes without requiring manual PID lookup.
Production htop Configuration Profile
By default, htop ships with generic settings that hide valuable columns such as detailed I/O rates and normalized load averages. Deploying a tuned htoprc configuration file to /root/.config/htop/htoprc provides an enterprise-ready dashboard layout from the moment you establish an SSH session:
# /root/.config/htop/htoprc - Enterprise Production Configuration
fields=0 48 17 18 38 39 40 2 46 47 49 1
sort_key=46
sort_direction=-1
tree_sort_key=0
tree_sort_direction=1
hide_kernel_threads=1
hide_userland_threads=0
shadow_other_users=0
show_thread_names=1
show_program_path=1
highlight_base_name=1
highlight_megabytes=1
highlight_threads=1
highlight_changes=1
highlight_changes_delay_secs=5
find_comm_in_cmdline=1
strip_exe_from_cmdline=1
show_merged_command=0
header_margin=1
screen_tabs=1
detailed_cpu_time=1
cpu_count_from_one=1
show_cpu_usage=1
show_cpu_frequency=0
show_cpu_temperature=0
degree_fahrenheit=0
update_process_names=0
account_guest_in_cpu_meter=1
color_scheme=0
enable_mouse=1
delay=15
hide_function_bar=0
header_layout=two_50_50
column_meters_0=AllCPUs2 Memory Swap
column_meter_modes_0=1 1 1
column_meters_1=Tasks LoadAverage Uptime DiskIO NetworkIO
column_meter_modes_1=2 2 2 2 2
Architectural Benchmarks: Comparing top, htop, and Netdata
Choosing the correct monitoring layer depends on whether you are conducting immediate interactive debugging during an outage or tracking longitudinal trends to forecast hardware capacity. The comparative matrix below highlights the operational trade-offs across the three dominant Linux monitoring tools:
| Feature / Metric | Standard / Default (top) | Tuned / Production (htop + Netdata) |
|---|---|---|
| Metric Resolution | 3.0s polling interval | 1.0s real-time per-second resolution |
| Historical Retention | None (transient snapshot only) | Days to months via dbengine compression |
| Process Tree Hierarchy | Unsupported / flat PID listing | Full parent-child tree visualization (htop F5) |
| Daemon CPU Overhead | 0% (runs only when invoked) | < 1.5% single-core CPU utilization (Netdata) |
| Automated Alerting Engine | None | Built-in threshold alerts (Slack, Discord, Email) |
| Kernel eBPF & Socket Tracing | Unavailable | Native eBPF plugin for filesystem and network I/O |
| Visualization Interface | Monochrome CLI text | Interactive CLI + Modern Web Dashboard (port 19999) |
Continuous Observability with Netdata: Per-Second High-Fidelity Telemetry
While htop excels at immediate manual inspection, it cannot capture intermittent micro-bursts, transient memory spikes that trigger the OOM killer at midnight, or creeping disk space exhaustion while you are away from the terminal. This is where Netdata establishes a production-grade telemetry foundation.
Netdata is an autonomous, ultra-lightweight observability agent written in optimized C. Unlike heavy APM solutions that require gigabytes of RAM and complex Java runtimes, Netdata collects thousands of metrics per second while consuming less than 1.5% of a single CPU core and approximately 150 MB of memory.
Core Architectural Advantages of Netdata on VPS Instances
- Sub-Second Resolution: Netdata collects, stores, and evaluates metrics every single second (1s granularity). Standard monitoring systems like Prometheus or Datadog typically poll at 15-second, 30-second, or 60-second intervals, completely missing micro-bursts that degrade web application responsiveness.
- Lockless Ring Buffer Time-Series Database (dbengine): Netdata stores time-series data using its custom
dbengine, which implements zero-copy in-memory caching coupled with highly compressed on-disk tiering. This allows a VPS with modest NVMe storage to maintain weeks of per-second telemetry data without I/O contention. - Automated Anomaly Detection: Netdata includes embedded machine learning models that continuously model baseline distributions for every individual metric, immediately flagging statistically anomalous behavior before it manifests as hard service failure.
- Auto-Discovery of Application Stacks: Netdata automatically detects and instruments local Linux services including Nginx, LiteSpeed, Apache, MySQL/MariaDB, PostgreSQL, Redis, and PHP-FPM without manual configuration.
SysAdmin Security Hardening: By default, Netdata binds its embedded web server to
0.0.0.0:19999, exposing server telemetry to the public internet if firewall rules are unconfigured. In enterprise production environments, always bind Netdata strictly to127.0.0.1and proxy the web dashboard through Nginx with TLS encryption and HTTP Basic Authentication, or restrict access via SSH port forwarding:ssh -L 19999:localhost:19999 user@vps-ip.
Hardened Production Netdata Configuration (/etc/netdata/netdata.conf)
Deploy the following optimized configuration file to /etc/netdata/netdata.conf. This configuration restricts network binding to localhost, disables unnecessary cloud reporting telemetry for privacy, optimizes the dbengine storage tier for low-memory VPS instances, and pins collector intervals to 1 second:
# /etc/netdata/netdata.conf - Hardened Low-Footprint Production Profile
[global]
    run as user = netdata
    history = 86400
    update every = 1
    memory mode = dbengine
    page cache size = 32
    dbengine multihost disk space = 512
    dbengine disk space = 512
    disconnect idle web clients after seconds = 60
    enable web elevation = no
    glibc malloc arena max for plugins = 1
    glibc malloc arena max for netdata = 2

[web]
    bind to = 127.0.0.1:19999
    default port = 19999
    mode = static-threaded
    web files owner = root
    web files group = netdata
    disconnect idle web clients after seconds = 60
    respect do not track header = yes
    x-frame-options response header = SAMEORIGIN

[cloud]
    conversation agent = no
    statistics = no
    anonymous statistics = no

[plugins]
    proc = yes
    diskspace = yes
    cgroups = yes
    tc = no
    idlejitter = yes
    charts.d = no
    python.d = yes
    go.d = yes
    node.d = no
    apps = yes
    ebpf = yes

[health]
    enabled = yes
    in memory max health log entries = 1000
    script to execute on alarm = /usr/libexec/netdata/plugins.d/alarm-notify.sh
Enforcing Systemd Cgroup Resource Quotas for Monitoring Daemons
Monitoring software should never become the cause of an outage. To prevent Netdata or its child collectors from exhausting CPU or memory during unexpected workload spikes, enforce deterministic resource constraints using a systemd drop-in override at /etc/systemd/system/netdata.service.d/override.conf:
# /etc/systemd/system/netdata.service.d/override.conf
[Service]
# Hard resource boundaries using cgroup v2
CPUAccounting=true
CPUQuota=25%
MemoryAccounting=true
MemoryHigh=384M
MemoryMax=512M
MemorySwapMax=0M

# Process scheduling and priority
Nice=19
CPUSchedulingPolicy=idle
IOSchedulingClass=idle
IOSchedulingPriority=7

# Security sandboxing
ProtectSystem=full
ProtectHome=true
PrivateTmp=true
CapabilityBoundingSet=CAP_SYS_PTRACE CAP_DAC_READ_SEARCH CAP_NET_ADMIN
After creating the override file, reload the systemd daemon and restart Netdata:
systemctl daemon-reload
systemctl restart netdata.service
systemctl status netdata.service
Linux Kernel Sysctl Tuning for Telemetry and Memory Protection
High-resolution monitoring requires proper kernel tunables to ensure unprivileged profiling tools can extract process metadata without risking kernel panics or swap thrashing. Apply the following parameters to /etc/sysctl.d/99-vps-monitoring.conf:
# /etc/sysctl.d/99-vps-monitoring.conf - Kernel Observability & Virtual Memory Tuning

# Minimize aggressive swap thrashing on low-memory VPS instances
vm.swappiness = 10
vm.vfs_cache_pressure = 50

# Ensure memory overcommit does not crash critical database processes
vm.overcommit_memory = 0
vm.overcommit_ratio = 50

# Increase maximum process ID allocation for high-concurrency threading
kernel.pid_max = 65536

# Enable unprivileged eBPF for Netdata kernel tracepoints
kernel.unprivileged_bpf_disabled = 0
kernel.perf_event_paranoid = 1

# Protect dmesg output while allowing monitoring service access
kernel.dmesg_restrict = 0

# Prevent panic on OOM; prioritize kill order
vm.panic_on_oom = 0
Load the updated kernel parameters immediately without rebooting:
sysctl -p /etc/sysctl.d/99-vps-monitoring.confOperational Playbook: Diagnosing the 4 Critical VPS Bottlenecks
When alerting triggers during production operations, follow this deterministic four-step triage playbook using htop and Netdata to identify and remediate the underlying failure mode:
1. Triaging High CPU Steal Time (%st > 5%)
Symptom: System load average spikes dramatically, but the sum of user (%us) and system (%sy) CPU utilization remains low. Web response latency degrades across all endpoints.
Diagnostic Flow:
- Open
htopand observe the CPU meter color bar. Look for the cyan segments representing steal time. - Navigate to the Netdata dashboard under CPU → CPU Steal. Examine whether the steal spikes occur at regular periodic intervals (indicating a neighboring VPS running intensive cron jobs) or continuous saturation.
- Verify hypervisor scheduling latency by executing:
grep "steal" /proc/statover a 10-second interval. - Remediation: CPU steal cannot be resolved by application tuning because the bottleneck exists at the physical hypervisor layer. The only permanent resolution is migrating workloads to an infrastructure provider like MeraHost that enforces strict anti-oversubscription policies and guarantees dedicated hardware execution.
2. Identifying Uninterruptible Disk I/O Saturation (D State Processes)
Symptom: Commands hang when attempting directory traversal, database queries queue indefinitely, and iowait exceeds 20%.
Diagnostic Flow:
- Launch
htopand pressF6to sort by IO_RATE or pressShift + Pto inspect process states. - Locate processes marked with the state flag
D. Unlike sleeping processes (S), processes inDstate are waiting directly on synchronous disk reads/writes or filesystem journal commits. - Check Netdata under Disks → Disk I/O and Disk Backlog. If disk queue depth exceeds 4 requests continuously, the underlying storage tier is saturated.
- Remediation: Identify the write-heavy process (e.g., unindexed MySQL slow queries, unbuffered log writes). Enable write buffering in application configs, partition logging to separate tmpfs mounts, or migrate to pure enterprise NVMe storage.
3. Diagnosing Memory Leaks and Swap Thrashing
Symptom: Free memory approaches zero, swap usage rises steadily, and database daemons unexpectedly restart due to kernel OOM kills.
Diagnostic Flow:
- Open
htopand examine the memory bar. Distinguish between green (active allocations) and orange (reclaimable cache). If orange dominates, memory is not depleted. - Press
Shift + Minhtopto sort processes strictly by resident memory consumption (RES). Look for memory growth over time in worker pools. - In Netdata, open Memory → System Memory and cross-reference Page Faults. A rapid rise in major page faults indicates the kernel is actively reading pages from slow swap disk, severely degrading execution speed.
- Review recent kernel OOM termination events:
dmesg -T | grep -i "oom-killer". - Remediation: Cap process worker lifecycles (e.g.,
pm.max_requests = 500in PHP-FPM) to flush memory leaks, and tunevm.swappiness = 10to keep memory pages in physical RAM.
4. Detecting Ephemeral Socket and Network Backlog Saturation
Symptom: Clients report intermittent “Connection Refused” or SSL handshake timeouts while CPU and memory metrics appear completely normal.
Diagnostic Flow:
- In Netdata, navigate to IP → TCP Sockets and TCP Errors.
- Inspect the count of sockets in
TIME_WAITandCLOSE_WAITstates. A massive accumulation ofTIME_WAITsockets indicates backend reverse proxies are closing connections without persistent HTTP keep-alive. - Check for TCP backlog drops:
netstat -s | grep "listen queue". - Remediation: Increase
net.core.somaxconn = 65535and enable TCP socket reuse vianet.ipv4.tcp_tw_reuse = 1in sysctl.
Frequently Asked Questions: VPS Resource Monitoring
Does running Netdata 24/7 impact VPS performance on low-spec instances?
No. Netdata is written in highly optimized C with lockless circular ring buffers and asynchronous multi-tier storage engines. On a standard 1-vCPU / 1GB RAM virtual server, Netdata typically consumes between 0.8% and 1.5% of single-core CPU capacity and less than 150 MB of memory. By applying the systemd cgroup resource slice override provided in this guide, you can strictly constrain Netdata to a maximum of 25% CPU quota and 384 MB memory ceiling, guaranteeing zero interference with your production web applications.
Why does htop report high memory usage when free -m shows ample available RAM?
This is a common point of confusion in Linux memory management. The Linux kernel follows the philosophy that unused RAM is wasted RAM. When physical memory is not required by active applications, the kernel allocates it to buffer cache and page cache to accelerate disk read operations. htop represents this cache visually as orange segments on the memory meter. This cached memory is instantly reclaimable by the kernel whenever an application requests new memory allocations. As long as resident application memory (green) is within safe limits and swap is unused, high cache utilization is normal and beneficial.
How do I securely access the Netdata web dashboard without exposing port 19999?
Never expose port 19999 directly to the public internet without authentication. The recommended enterprise approach is to bind Netdata strictly to 127.0.0.1:19999 in /etc/netdata/netdata.conf. To view the dashboard securely, create an encrypted SSH tunnel from your local workstation: ssh -L 19999:localhost:19999 root@your-vps-ip. Once connected, access http://localhost:19999 in your local browser. Alternatively, configure an Nginx reverse proxy with Let’s Encrypt SSL, IP whitelisting, and HTTP Basic Authentication.
What is the practical difference between CPU steal (%st) and I/O wait (%wa)?
While both metrics represent waiting states, their underlying causes are completely different. CPU steal (%st) occurs when your virtual machine has executable code ready to run, but the host hypervisor is unable to grant execution time because the physical CPU is busy running tasks for other virtual servers on the same node. Conversely, I/O wait (%wa) means your virtual CPU is intentionally idling because your own processes are blocked waiting for disk storage or network filesystem operations to complete. High steal indicates host hardware oversubscription, whereas high iowait indicates disk throughput saturation or inefficient application queries.
When architecting business-critical infrastructure, continuous monitoring is only half the equation; the underlying hardware platform must provide guaranteed compute cycles and deterministic storage performance. If your monitoring metrics frequently reveal CPU steal spikes or I/O wait bottlenecks on legacy cloud providers, consider migrating your production instances to MeraHost Enterprise Cloud. With dedicated NVMe arrays, unthrottled gigabit networking, and zero price hikes since 2012, MeraHost delivers the stable baseline your telemetry deserves.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).
Leave a Comment